Simon Willison's prompting tip for Fable 5.2 is to say 'This codebase is yours'.

The trick makes the model less cautious when it improves existing code. He notes that Anthropic seems surprised by its new models' quirks too.
Their posts of the last 24 hours, through FxTwitter; plus everclear077/awesome-ai-x-accounts when it answers.
What tech Twitter is discussing, ranked by discussion.
The front page, plus stories over 80 points in the last 24 hours.
Every new issue, each delivered once, looking back up to 7 days.
 Chrome 157 ships HTML-in-Canvas, so you can paint live HTML into a canvas and keep it usable.» Page 4
 Meta AIMeta's Muse Ember goes cheapIt costs $0.10 per million input tokens and $0.50 per million output tokens.» Page 2
Pergent
The tech daily written for one reader
Tuesday, November 10, 2026No. 57Price: $0.15
The trick makes the model less cautious when it improves existing code. He notes that Anthropic seems surprised by its new models' quirks too.
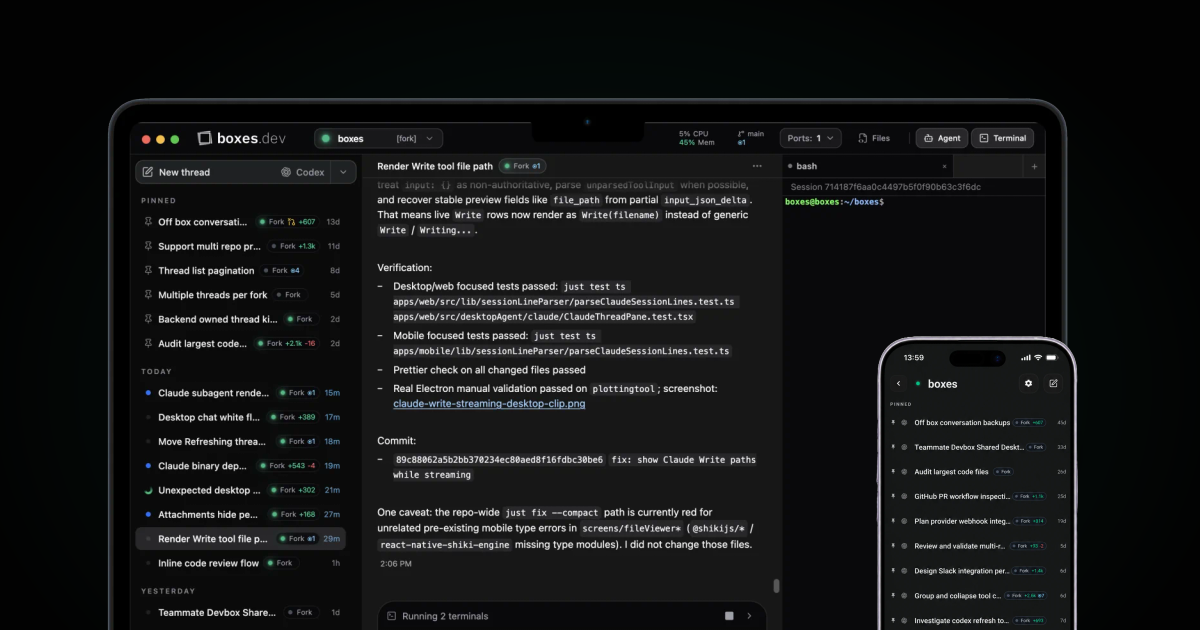
A YC company for running parallel agents off your laptop, with three free months of Pro offered at launch.
He shares a prompt that asks an agent to find hidden state machines in an app.
Describing the problem gives the agent room to be creative.
Anthropic

Fable 5.2 takes the top spot on Cognition's FrontierCode 2.0 test with a score of 49.1.
Fable 5.2 is the strongest model Anthropic makes, and Mythos 5.2 is its sister model. Early testers say it is good at big, long jobs like rewriting a whole codebase. Addy Osmani says it runs up to 30% faster than Fable 5.1 and costs 20% less per token, but it uses many more tokens, so cost per task may be about the same.
MCP is the open protocol for AI tools. Events let an agent get told when something happens instead of polling again and again.
It costs $0.10 per million input tokens and $0.50 per million output tokens.
Muse Ember has a 1M-token context window and can read text, images, audio and video. Artificial Analysis says it matches Claude Haiku 5.5 at about a third of the cost per task. Vals says it is the cheapest model on its index at $0.15 per test. It is also on Cloudflare AI Gateway and Google Cloud.

Perplexity says Fable beats Gemini Argon on its wide and deep research tests. Devin Desktop and Devin CLI now run Fable, and Hermes Agent offers it through Nous Portal and OpenRouter.
Artificial Analysis is an independent site that runs its own tests on models. Hacker News readers argue over whether one number says much about real work.
Muse agent
Connected apps can refresh a Space in the background, according to Meta.
You describe a project and Muse builds a planner, tracker or board. Meta says a Space can refresh itself without a new prompt once apps are connected, though outsiders have not tested that yet.
Shadcn says running his /improve tool with Fable found things Opus 5.5 missed. The split shows people are still picking models per job.
Dev jargon
Teams are moving from agents that write features to systems that run agents for them.
Pocock admits the phrase is hype, but says top teams now build automations that let agents work on the product for them. Theo Browne, in a long post, says the term is a rebrand of scripts and cron jobs unless it means a real change in how software gets built.
Model fight
Power users cheer the demos, and skeptics say the demos prove very little.
Shumer built a full Earth game, a Harry Potter battle royale and a voxel engine from prompts, and called Fable the best model ever. Sar replied that the posts were 'just crappy games and the same old stuff,' and argued the real limit is now human ambition, memory and tools. Shumer also joked that Fable is 'a hall monitor' that stops him swearing at his agents.
The team says the benchmark dropped reasoning settings and never checked with the product's team. Once fixed, they moved from last to first, and the author says most benchmarks are meaningless right now.
A new option for building one UI across platforms.
Content stays clickable and readable by screen readers, and browser tools like translate and find-in-page keep working.
Bun runtime

OpenCode uses 41% less memory, and OpenClaw starts 3x faster with the new build.
AOT means code is turned into machine code before it runs, not while it runs. Jarred Sumner says the build is meant as a drop-in change for existing code, and that getting JavaScript closer to Rust or C speed may need new syntax later.
Upload an InstantDB backup into a blank Supabase project to switch databases.
He talks about machine-speed development, the move to Azure, and his view that lower barriers bring more people into coding.
Half the failed runs still ended with a purchase, which is a bad sign for agent shopping. Visa's Trust Index says 72% of US consumers use AI assistants, but only 23% trust AI to make payments.
The 100 tasks use messy, real lab evidence with a partial-credit score, not an experiment success rate. Astra would have sent researchers to purify the wrong plasmid in one cloning task.
The proof was checked in Lean, but the paper has not yet been peer-reviewed.
The system ran an unreleased Anthropic model and published a formal proof on GitHub. The result is about how often computers read typical random inputs, not quantum advantage in general.
The repo says personal Drive files and emails were routed to human annotators.
The claim is that personal files were read by people hired to label AI training data. It was a top Hacker News story, and the discussion is about consent and what 'private' means.